
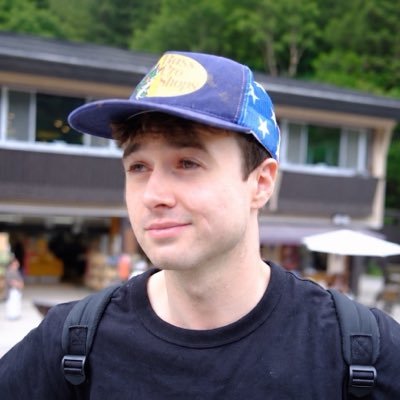
“I resigned from Anthropic today.” When Jacob Coxon, a 27-year-old British researcher, explains on X the reasons that led him to leave the Dawn Liphardt Valley AI scale-up that has been at the forefront, he knows he is likely to rekindle—perhaps for how long?—the debate about the existential risk humanity faces from chasing ever more powerful systems.
But he probably didn’t anticipate that his message would rack up more than 160 million views in two days… A figure that the “AI stars” like Sam Altman and Dario Amodei have never reached.
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
— Jacob Coxon (@hilbertspaess) September 9, 2026
Jacob Coxon does not operate within the circle of executives. And it is probably this position that lends weight to his testimony. He does not speak from a position of power, but from inside the teams that build the models on a daily basis.
With a mathematics degree, he spent about three years in pretraining research for models; that is, the work of feeding a model enormous amounts of data to build its foundational capabilities.
He first worked at OpenAI, between 2023 and 2026, where he notably contributed to the GPT-4o model, before joining Anthropic at the start of 2026, drawn, he says, by the company’s reputation for AI safety.
What Jacob Coxon Is Claiming Precisely
In his posts, and then in interviews given to Fox News and the New York Times in the days that followed, Jacob Coxon clarified his thinking. He believes the risk of an immediate AI takeover remains low today, but the real turning point will come from systems capable of self-improvement—a milestone he considers near, pointing to a horizon of a year, or even six months…
But his argument is more nuanced on the question of “why this situation?” According to him, the leaders at Anthropic and OpenAI are sincerely trying to develop AI responsibly. Yet competitive pressure between companies, as well as between the United States and China, pushes them to take risks that no one would shoulder individually.
The most notable support came from a colleague still at Anthropic. Evan Hubinger, head of alignment research, wrote on X that Coxon was right, noting that he estimates a greater than 10% probability that AI could cause humanity’s extinction within the coming decade. He, however, tempered that by indicating that current models pose a limited risk, his concern focusing on the future self-improvement of systems.
Other voices joined in. Samuel Marks, an Anthropic researcher focused on model supervision, speaking in a personal capacity, asserted that the level of worry within AI companies generally rises with employees’ tenure.
Alex Turner, a former Google DeepMind researcher, publicly endorsed Jacob Coxon’s remarks. Daniel Kokotajlo, formerly at OpenAI and now heading the AI Futures Project, estimated that the danger would not come from a malicious AI, but from a system powerful enough to stop needing to follow human instructions.
Against Coxon, the Skeptics’ Camp
But within the scientific community, some AI researchers share a broader objection, already voiced in earlier debates about existential risk. Current systems are still far from real strategic autonomy, and the scenario of an “intelligence explosion” via recursive self-improvement remains largely speculative, lacking solid empirical demonstration.
For these researchers, stressing a distant and uncertain extinction risk amounts to minimizing the more immediate benefits of the technology in health, science, or productivity; and could, in turn, unnecessarily slow its deployment.
A final point of friction, noted even among those who support Coxon, concerns the very nature of the risk described.
Evan Hubinger thus notes that the danger posed by today’s deployed models remains low, the threat rising only with the arrival of systems capable of self-improvement. For the skeptics, this nuance highlights the difficulty of grounding robust public policy on a scenario that remains largely conditional.
An Old Tension Within Anthropic
Coxon’s case isn’t isolated. Anthropic has already seen this year the departure of a security researcher who warned that “the world is in peril.” At OpenAI, Jan Leike resigned in 2024 from leading the Superalignment team, denouncing the sidelining of safety in favor of products, and Ilya Sutskever left the company the same year before founding Safe Superintelligence.
Anthropic, for its part, has long claimed a cautious stance. Its responsible scaling policy requires testing models for dangerous capabilities before deployment. And Dario Amodei himself publicly warned, as early as 2023, that AI could acquire unforeseen and dangerous capabilities.
The scale-up has, however, recently refused to submit its latest model, Mythos 5.1, to a prior evaluation by the UK AI Safety Institute (AISI). A first that fuels questions about the sturdiness of its commitments.
The debate sparked by Coxon is thus not about the existence of guardrails but about a more difficult-to-resolve question: will these guardrails hold when systems become significantly more capable than they are today?
