
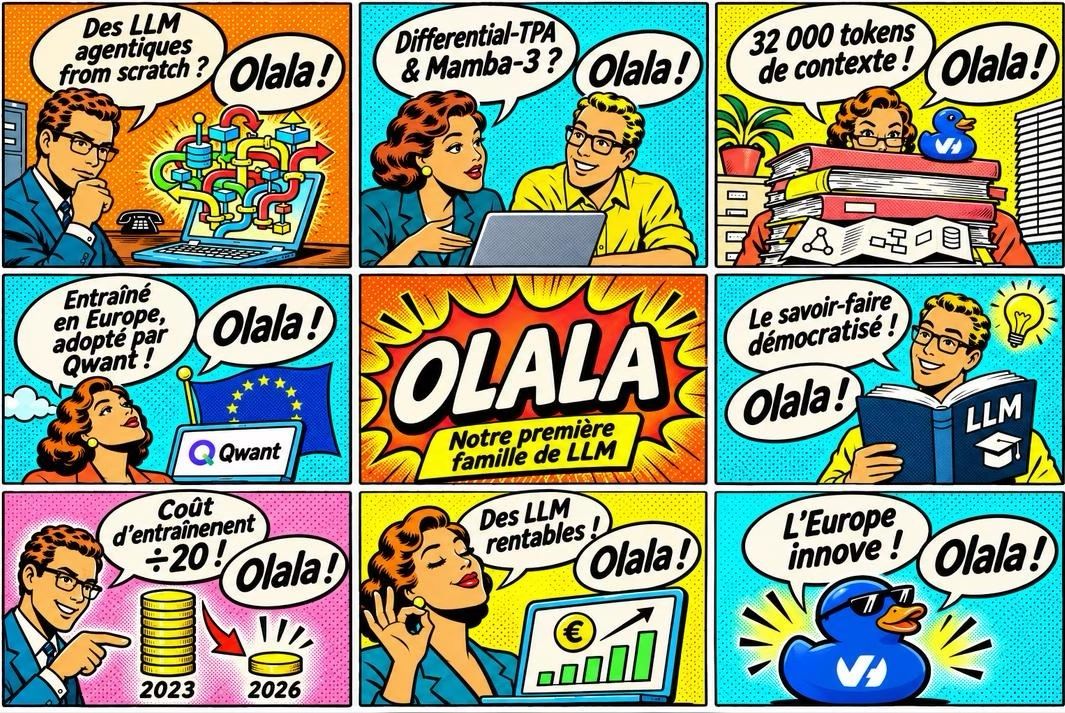
The know-how around training models has become widely democratized, and the cost of training has been cut by a factor of 20 in just three years. It is now possible to build LLMs while keeping this activity profitable, according to the founder-CEO of OVHcloud. This is one of the reasons cited for launching Olala.
In this family of large language models (LLMs), the first offspring was christened Olala mini 7A1B. According to OVHcloud, it is designed to operate with a reduced compute and memory footprint, including on gear that does not necessarily feature a dedicated GPU.
Olala mini 7A1B is built on a 7‑billion-parameter architecture, with 1 billion activated per query. These parameters are distributed across 256 experts per layer, following a Mixture-of-Experts approach: only a fraction of the model is engaged during processing.
The model also features a hybrid attention mechanism that combines Differential-TPA and Mamba-3. According to OVHcloud, this design helps reduce memory consumption and accelerate inference. The model is released in BF16 format, with a context window of 32,000 tokens.
OVHcloud notes that Olala mini can run on a GPU with at least 8 GB of memory. On an NVIDIA RTX A4500, the company reports a throughput of 160 tokens per second. On a plain CPU, without a GPU, it achieves 50 tokens per second.
However, no independent benchmark results are presented at this stage.
Olala mini was trained on three European public supercomputers: Jupiter, MeluXina, and Jean Zay, equipped with GPUs GH200, A100 and H100. OVHcloud estimates that this support amounts to the equivalent of €7 million in compute hours.
The company presents this initiative as enabling the formation of its AI team and the creation of the OVH Agentic Lab: OVHai LLM.
A publication under the Apache 2.0 license
Olala mini will be published on Hugging Face under the Apache 2.0 license. OVHcloud plans to release the model weights, its pre-trained base model, a technical report, and a documentation of compliance with the AI Act.
The Qwant search engine already indicates that it uses it for its quick-response feature.
A version 1.1 is expected by the end of the year. It should push the context window to 128,000 tokens and enhance the model’s mathematical reasoning capabilities.
In the longer term, the 2.0 release is expected to surpass 100 billion parameters. OVHcloud foresees specialized variants for enterprise agentics, cloud DevOps, and cybersecurity, spanning both defensive and offensive aspects.
